Zichen Zhou 周子琛
First-Year Master's Student 硕士一年级研究生
Hi! I am a first-year master's student at Beijing Institute of Technology. My research interests mainly focus on Embodied AI and Robotics, particularly developing Vision-Language-Action Models and Visuomotor Policies for dexterous manipulation in real-world scenarios. 您好!我是北京理工大学的一名硕士一年级研究生。我的主要研究兴趣集中在具身智能 (Embodied AI)和机器人学 (Robotics)。我致力于开发针对真实世界灵巧操作的视觉-语言-动作模型和视觉运动策略。
Latest News最新动态
Publications 论文发表
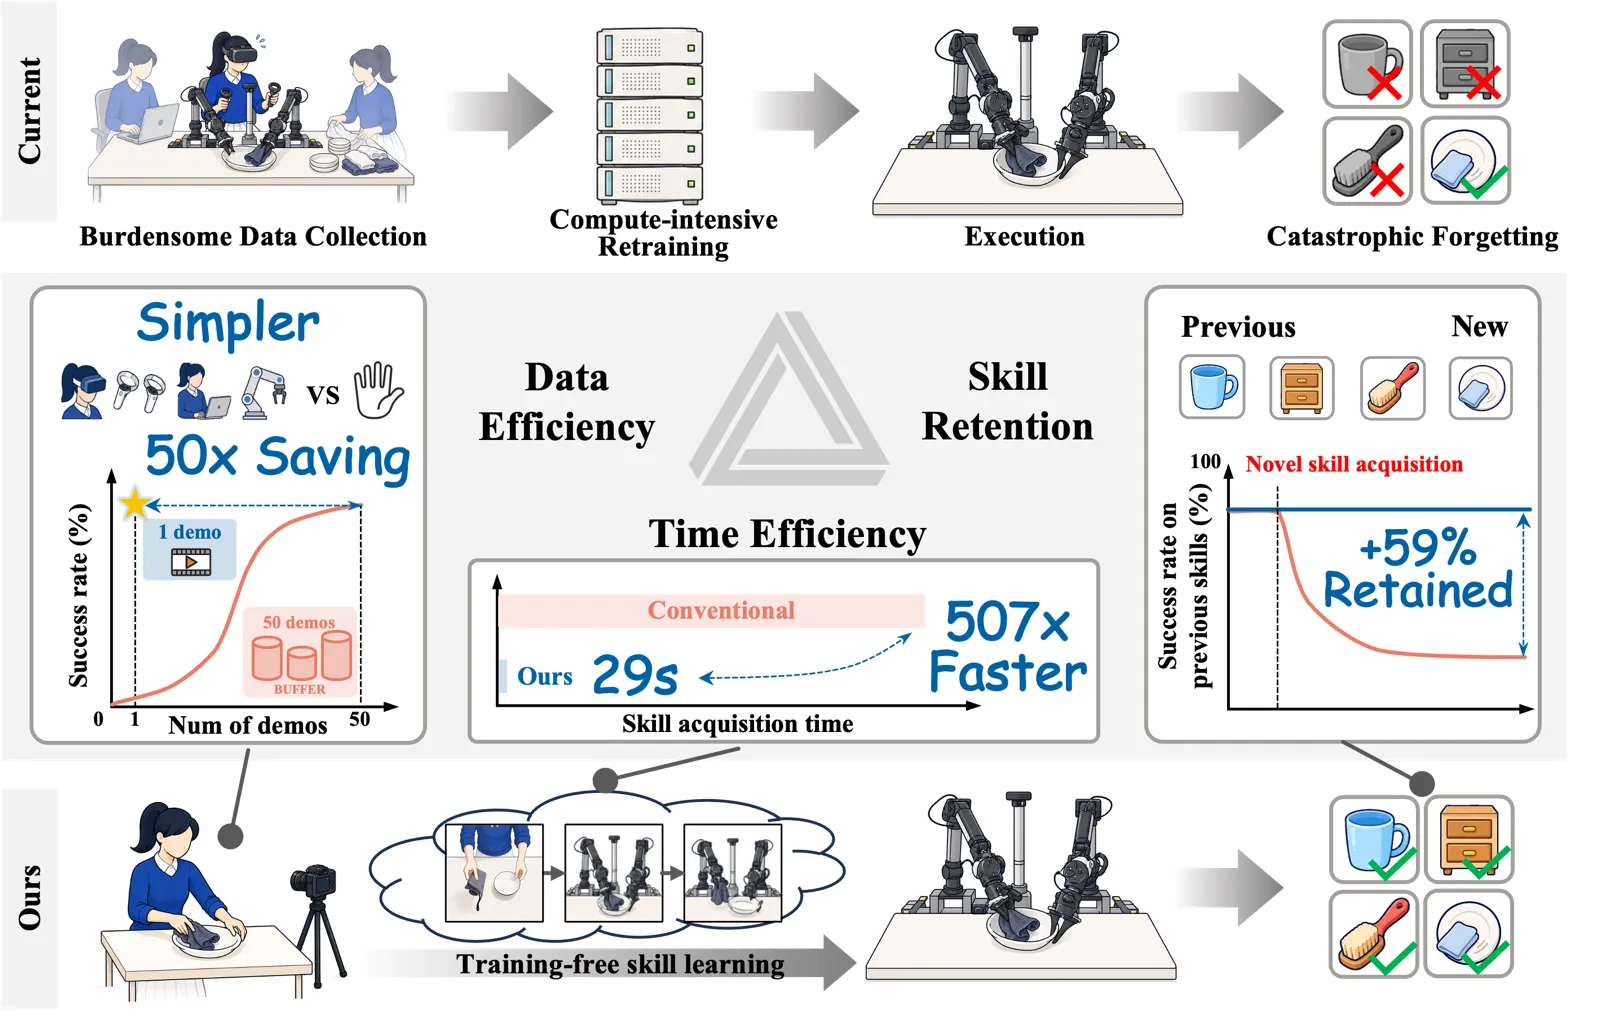
Robots Acquire Manipulation Skills in Seconds from a Single Human Video
G Chen, M Wang, T Cui, Zichen Zhou, Q Shao, X Li, H Su, R Gan, H Wang*, M Fu*, Y Yang*, Y Yue*
arXiv preprint arXiv:2607.20033, 2026. arXiv preprint arXiv:2607.20033, 2026.
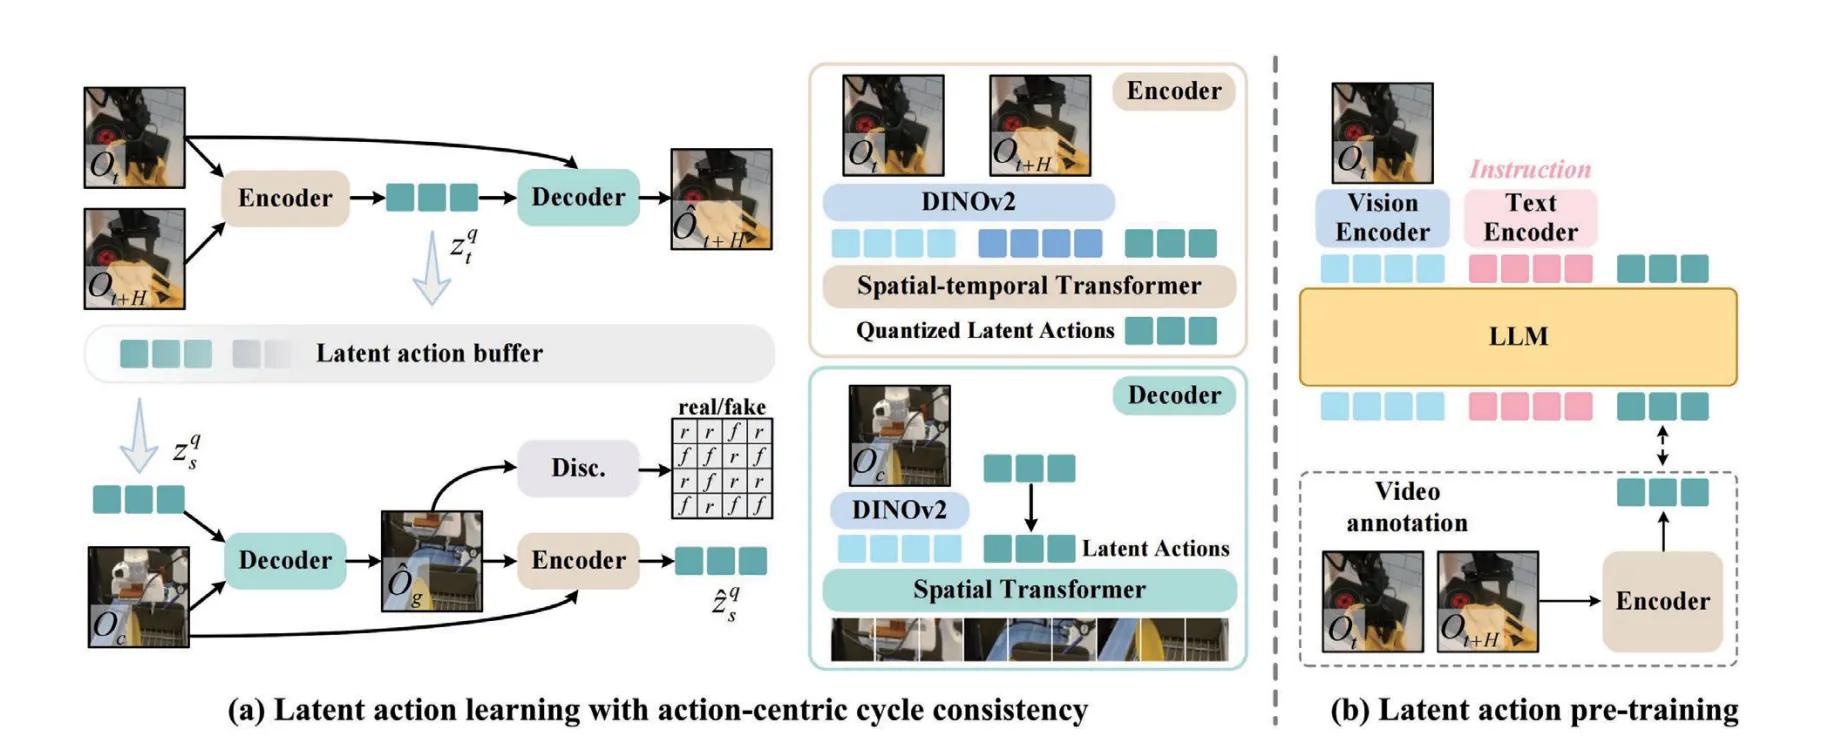
Learning a Unified Latent Action Space from Videos with Action-centric Cycle Consistency
G Chen, Q Shao, T Cui, Zichen Zhou, W Mao, L Yang, M Wang, Y Yang, H Chen, Y Yue*
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026.
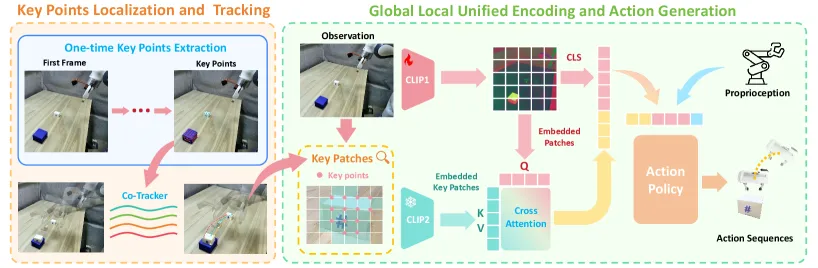
GLUE: Global-Local Unified Encoding for Imitation Learning via Key-Patch Tracking
Y Chen, Zichen Zhou, J Dou, T Cui, Y Yang, Y Yue
IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2026. IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2026.
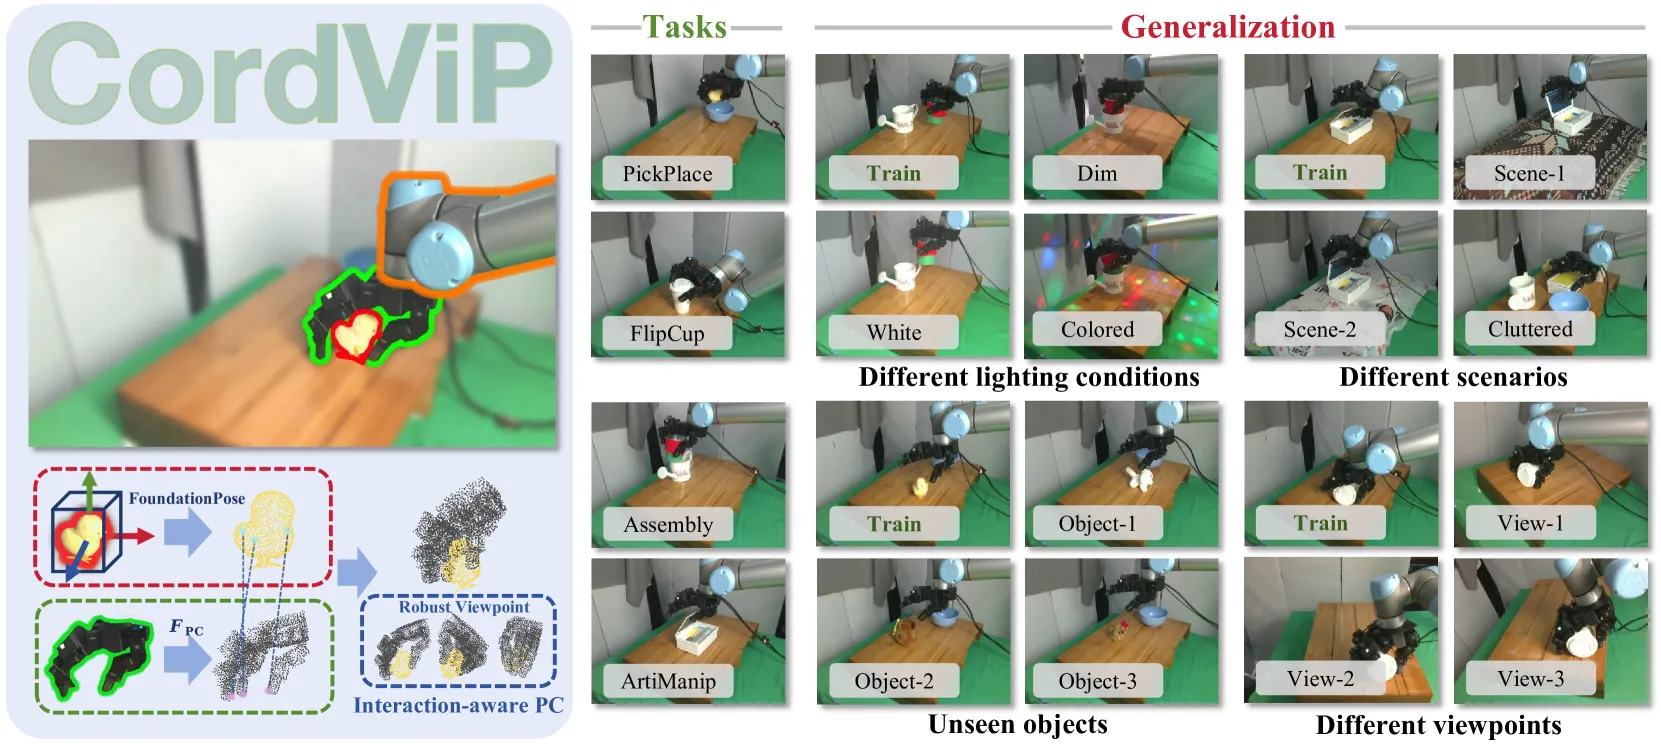
CordViP: Correspondence-based Visuomotor Policy for Dexterous Manipulation in Real-World
Y Fu, Q Feng, N Chen, Zichen Zhou, M Liu, M Wu, T Chen, S Rong, J Liu
Robotics: Science and Systems (RSS), 2025. Robotics: Science and Systems (RSS), 2025.
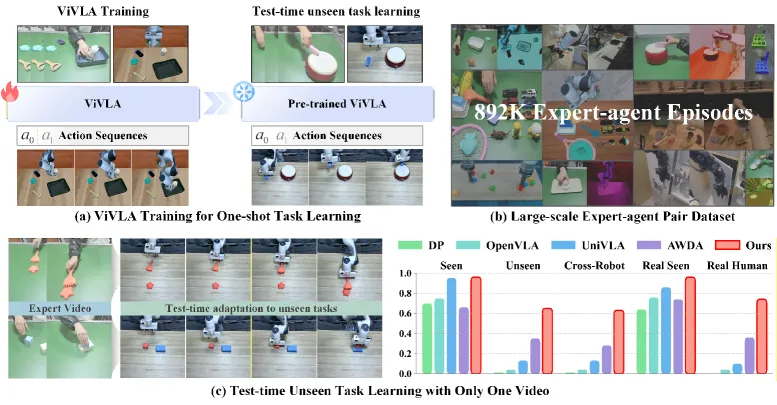
See Once, Then Act: Vision-Language-Action Model with Task Learning from One-Shot Video Demonstrations
G Chen, M Wang, Q Shao, Zichen Zhou, W Mao, T Cui, M Zhu, Y Deng, L Yang
arXiv preprint arXiv:2512.07582, 2025. arXiv preprint arXiv:2512.07582, 2025.
Awards荣誉奖项
- 2026.06
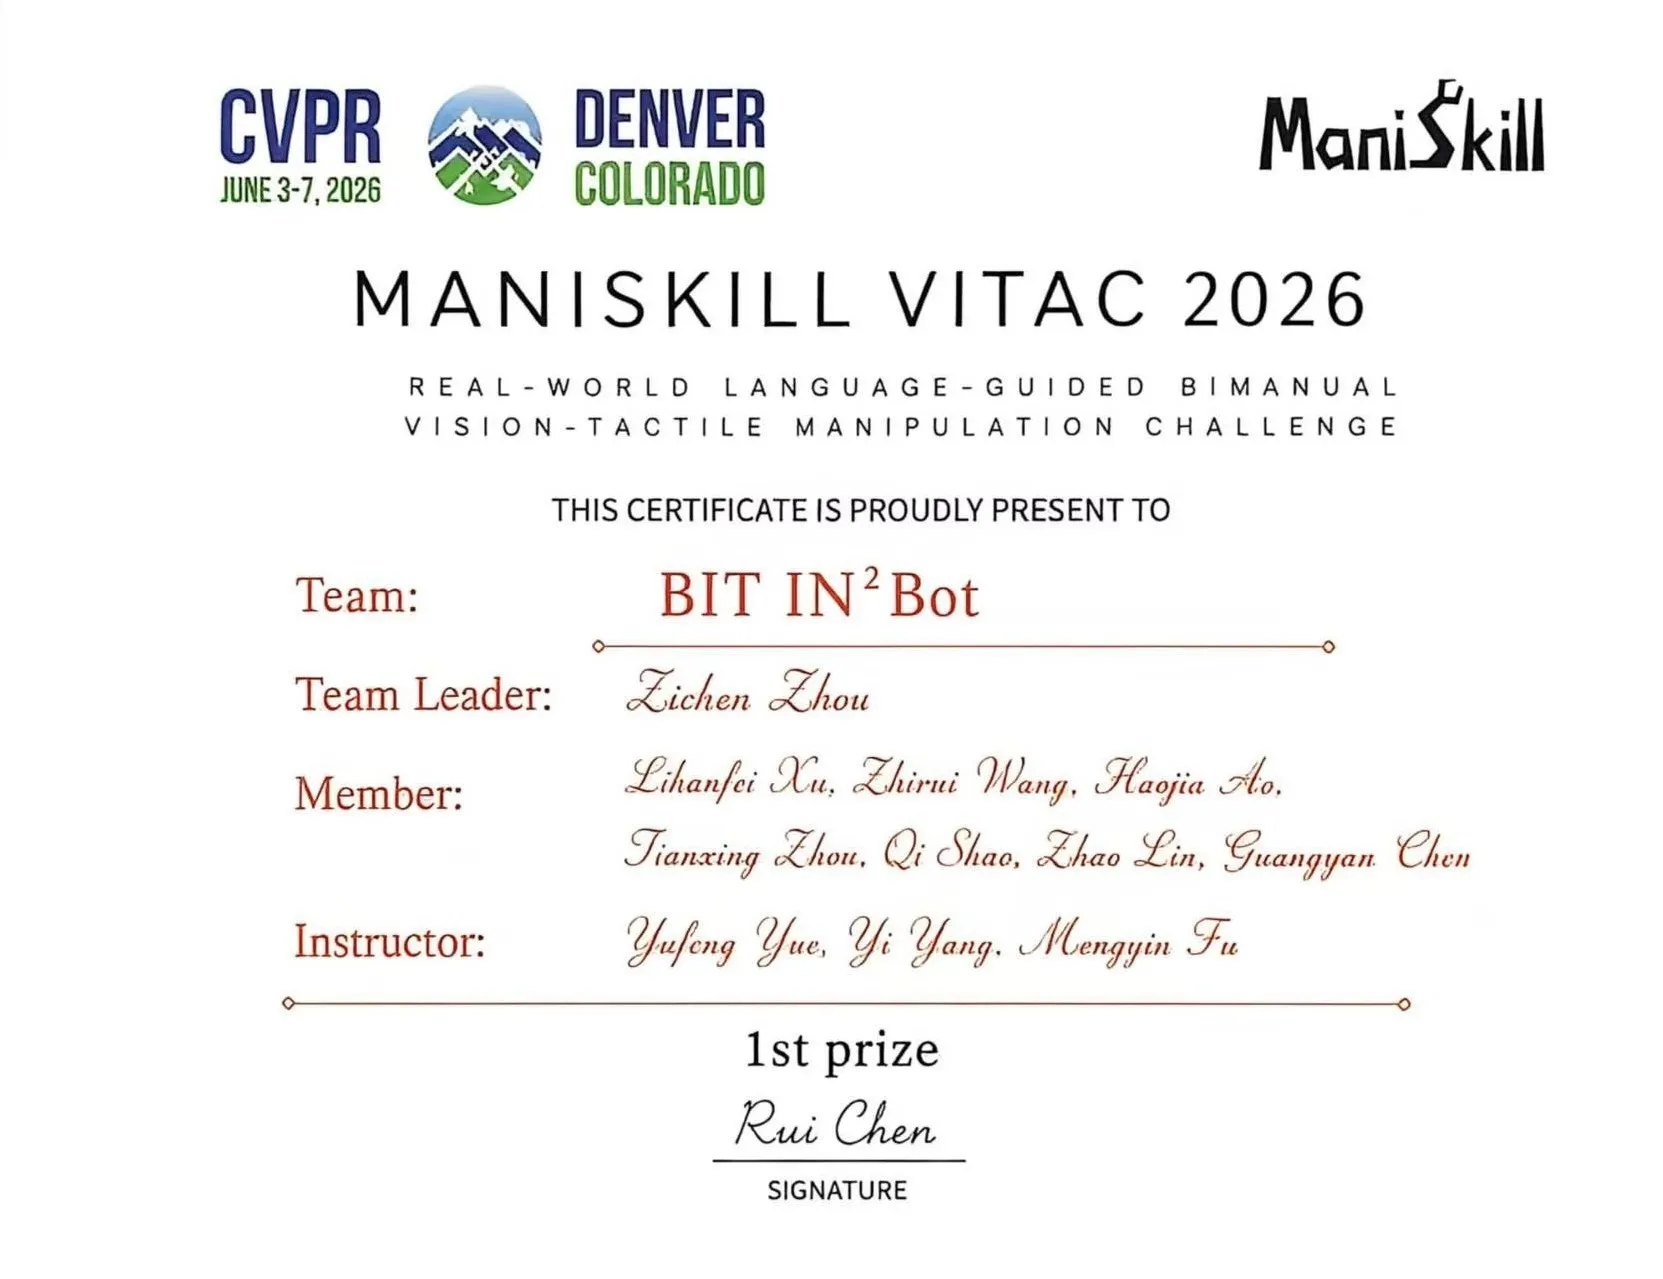
🏆 1st Place — ManiSkill-ViTac Challenge 2026 🏆 冠军 — ManiSkill-ViTac Challenge 2026
Won 1st Place at the ManiSkill-ViTac Challenge 2026 at the CVPR 2026 Embodied AI Workshop. Team: BIT IN²Bot. 在 CVPR 2026 Embodied AI Workshop 的 ManiSkill-ViTac Challenge 2026 中获得冠军。队伍:BIT IN²Bot。
Education & Experience教育与经历
Beijing Institute of Technology 北京理工大学
Sep 2026 - Present 2026.09 - 至今Master's Student 硕士研究生
First-year master's student researching embodied AI and robotics. 硕士一年级在读,研究方向为具身智能与机器人学。
X-Square Robot 自变量机器人 (X-Square Robot)
Mar 2026 - Present 2026.03 - 至今Research Intern 研究实习生
Focusing on Embodied AI and developing advanced visuomotor policies for robotic manipulation. 致力于具身智能方向的研究,开发用于机器人灵巧操作的先进视觉运动策略。
Beijing Institute of Technology 北京理工大学
Sep 2022 - Jun 2026 2022.09 - 2026.06Bachelor of Engineering 工学学士
Engaged in cutting-edge research in robotics and AI during undergraduate studies. 本科期间积极参与机器人与人工智能领域的前沿研究。
Visitor Stats 访客统计
Visitor locations 访客地区分布
Map widget pending — register at clustrmaps.com 地图组件待配置 — 请前往 clustrmaps.com 注册域名